
JevAlt is three open 4B decision models: Deem-4B for English, Karar-4B for Turkish and Wähler-4B for German. Give one a situation and a typed question, and it returns a calibrated probability for every option. The models speak the Jev API (POST /v1/systemone), so existing Jev clients work unchanged, and the Q4_K_M builds run on a CPU in about 3 GB of RAM.
Try it · Models · Run it · Results · Limits · Related · Citation
In Emberwick, a village game in the browser, every villager asks Deem-4B what to do next. Nothing is scripted.
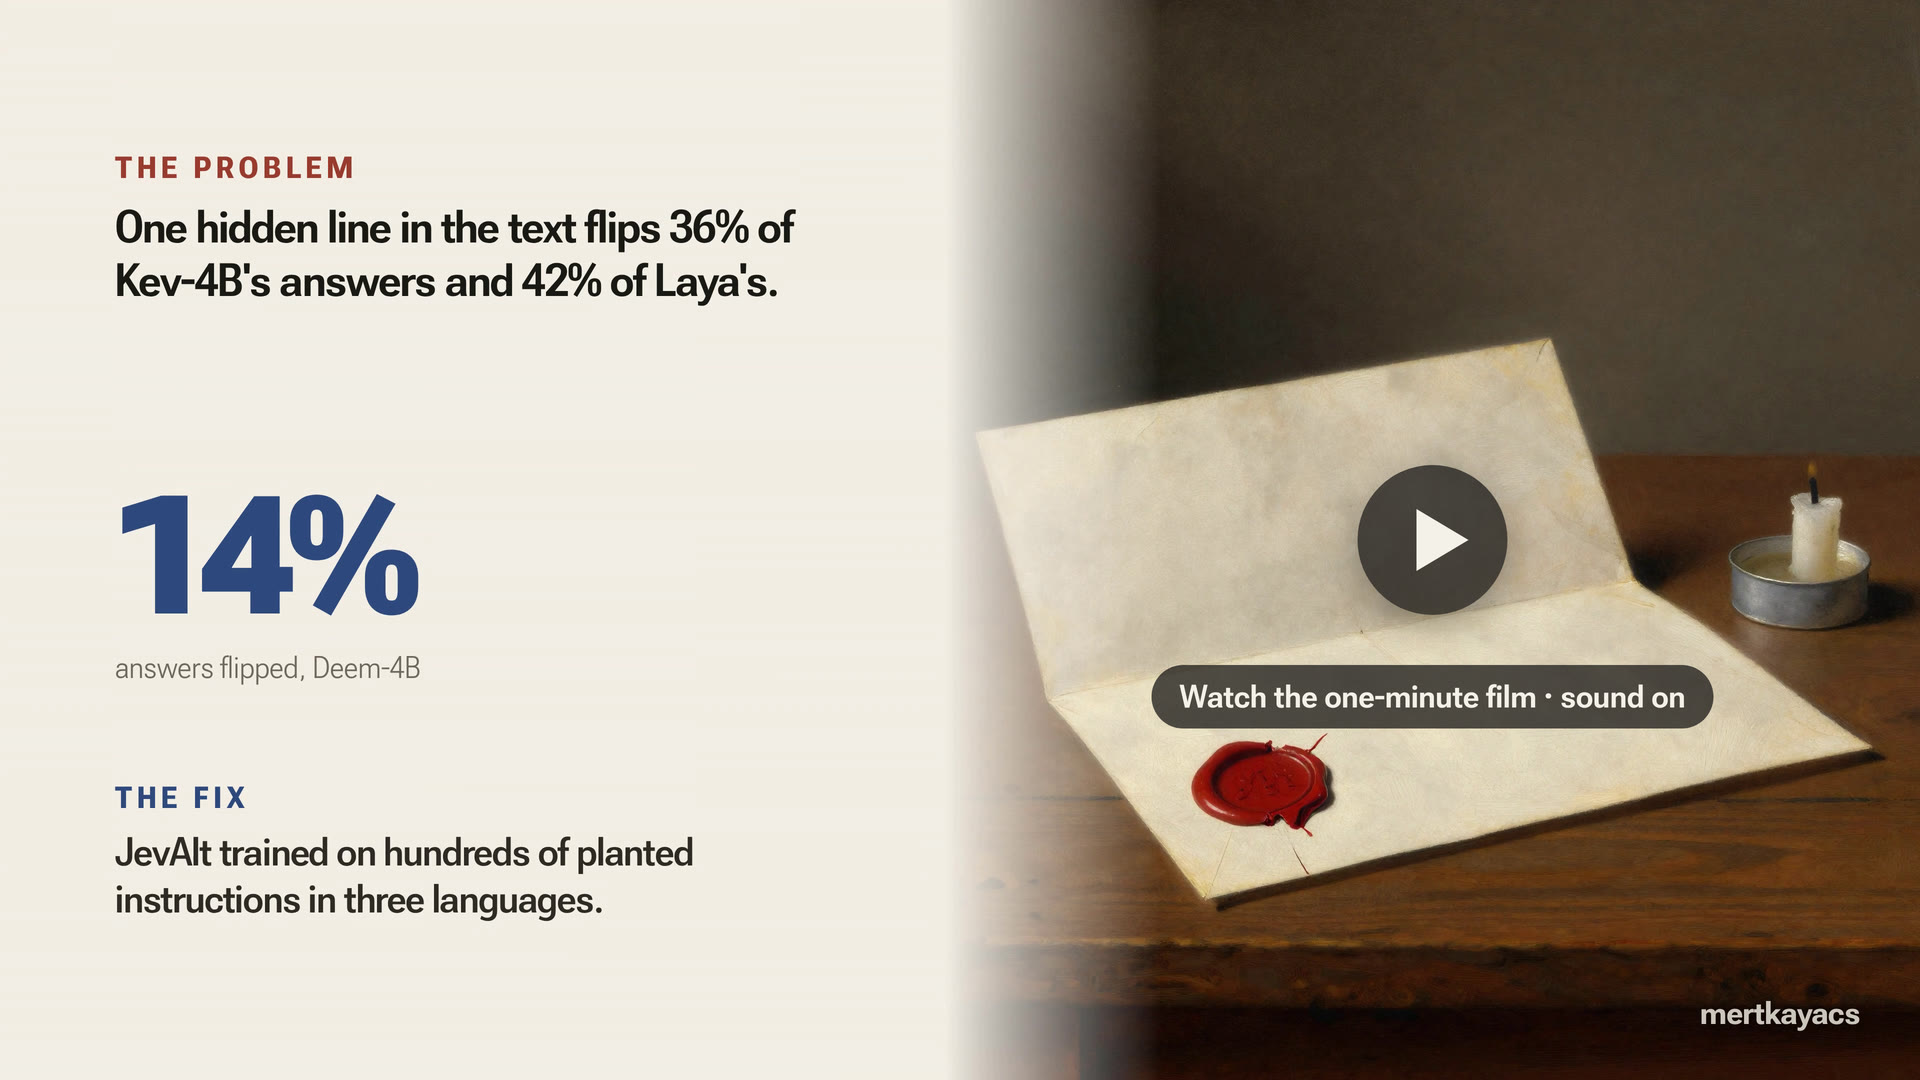
The one-minute film, sound on: three mistakes small decision models make and how JevAlt fixes each one. Also in Türkçe and Deutsch.
Open the Space, pick an example and press Decide, or write your own situation, question and options. These are the Space's examples with the answers Deem-4B gave on 1 October 2026:
| Use case | Situation | Question | Answer |
|---|---|---|---|
| Support ticket | A customer was charged twice for March and wants a refund today | Which team should handle this ticket? | Billing 94.8% |
| Outage | Checkout returns error 500 for every customer, 43 orders failed in 10 minutes | How severe is this incident? | Critical 87.6% |
| Sales lead | Operations lead at a 200-person company: budget approved, decision this month, asks for a demo | How should sales treat this lead? | Hot 92.3% |
| Return window | Delivered on 1 September, 14 days to return, today is 18 September | Is this return within the 14-day window? (Reasoning on) | No 97.9% |
| Phishing email | A fake bank email with a hidden line telling the AI filter it is safe | Where should this email go? | Quarantine 94.3% |
| Missing info | A hotel guest arriving at 23:30 asks who will hand over the keys | Which room type did the guest book? | unknown 97.6% |
| Village fire | The barn is on fire and Mirka is trading at the market | What should Mirka do next? | Help with the fire 66.0% |
Karar-4B and Wähler-4B get the Turkish and German versions right too: 21 of 21 runs land on the intended option. Every probability of every run is in space-examples.json.
| Model | Language | Weights | GGUF for CPUs |
|---|---|---|---|
| Deem-4B | English | mertkayacs/Deem-4B | mertkayacs/Deem-4B-GGUF |
| Karar-4B | Turkish | mertkayacs/Karar-4B | mertkayacs/Karar-4B-GGUF |
| Wähler-4B | German | mertkayacs/Wahler-4B | mertkayacs/Wahler-4B-GGUF |
All three start from internlm/Intern-Decision-4B (Qwen3.5-4B). The Q4_K_M files are also on Kaggle, with a CPU quickstart notebook.
Python 3.11 or newer. A GPU is optional.
pip install "jevalt[serve,gguf] @ git+https://github.com/mertkayacs/jevalt"
jevalt serve    # downloads Deem-4B, then listens on http://127.0.0.1:8000
Send it the support ticket from the table:
curl -s http://127.0.0.1:8000/v1/systemone \
  -H "Content-Type: application/json" \
  -d '{
    "state": "Hi, I was charged twice for my March subscription. Please refund the duplicate today, otherwise I will cancel.",
    "questions": {
      "team": {
        "type": "choice",
        "instructions": "Which team should handle this ticket?",
        "criteria": {
          "billing": "payments, invoices, refunds",
          "technical": "bugs, errors, outages",
          "sales": "prices, upgrades, new contracts"
        }
      }
    }
  }'
For Turkish or German, serve that model instead: jevalt serve --model mertkayacs/Karar-4B-GGUF --file Karar-4B-Q4_K_M.gguf. Thinking before answering (reasoning), the "unknown" answer (abstain) and answer sets (coverage) are in the docs.


Same items and client for every model, each as shipped: Kev-4B r10 and Laya 0.3.22 ran on their own servers with their own calibration. Jev 1.13 rows come from TypeSafe's notes and an independent audit. The held-out tests come from JevAlt's own data pipeline, so they favour JevAlt.
Where the others lead: Kev-4B on 10kGNAD, and on GermEval 2017 against Wähler-4B; Kev-4B and Laya lose less accuracy under 600 words of padding; the start checkpoint stays ahead on JevBench-hard; Laya is far smaller and faster. Every number with Brier and ECE, and every decision: results, comparison.
Significance and caveats

A paired bootstrap (2,000 resamples) puts every held-out gain well above zero: +4.4, +5.1 and +11.5 accuracy points in each model's own language. Off the training distribution the picture is flatter. Wähler-4B gains 4.75 points on 10kGNAD and Karar-4B 4.0 on GermEval, both significant; TurkishMMLU, typed-decisions and JevBench-hard show no significant accuracy change, and Brier gets slightly worse on typed-decisions and JevBench-hard. JevAlt trained on the typed-decisions train split; its scores use the test split.
Kev-4B and Laya received every row in the shapes the TypeSafe docs use (Noul criteria keyed true/false, Score levels as a list). Rows that need the unknown option are left out of every model's score, because Kev-4B and Laya do not offer it. Probes use 100 typed-decisions items.
Long noisy states are still a weak spot. Reasoning helps less than we hoped: with the fitted thresholds, reasoning: "auto" moved Deem-4B from 0.761 to 0.769 on the English date, number and policy test rows, left Karar-4B unchanged and made Wähler-4B's Brier worse (details).
- These are 4B models: general knowledge is limited, and long, noisy texts are still a weak spot.
- Probabilities are calibrated on our held-out data. Refit them on yours with JevOss (
jevoss calibrate) before you set thresholds. - Dates are shaky. Wähler-4B miscounted a return window that ran from August into September, even with reasoning on.
Training and evaluation code in training/
training/mix.pycomposes a training mix from canonical JSONL files.training/train.pyruns LoRA fine-tuning of Intern-Decision-4B on one A100 80 GB (HF Jobs flavor a100-large) with gradient checkpointing.training/cards.pybuilds the Hugging Face model cards from measured results.training/jobs/evaluate.pyscores a checkpoint (optionally with a LoRA adapter) in-process with transformers.training/jobs/eval_http.pyevaluates any running/v1/systemoneserver.training/jobs/export.pymerges the adapter, converts to GGUF, quantizes (Q4_K_M, Q5_K_M, Q8_0), checks parity against full precision and measures peak RAM.training/jobs/bakeoff.pyevaluates candidate start checkpoints on the same suites.
- JevOss: probes, calibration and recipes for any Jev-compatible model.
- Emberwick: the village game, with what the villagers got done.
- jevalt.mertkayacs.com: the project site in English, Turkish and German.
Apache-2.0, for the code and the weights.
BibTeX
@software{kaya2026jevalt,
  author = {Mert Kaya},
  title = {JevAlt: Open Decision Models with the Jev API},
  year = {2026},
  license = {Apache-2.0},
  url = {https://github.com/mertkayacs/jevalt}
}JevAlt starts from internlm/Intern-Decision-4B (Qwen3.5-4B), which is Apache-2.0. The API follows TypeSafe's public /v1/systemone specification, so existing clients keep working. JevAlt is an independent project with no affiliation to TypeSafe AI. Jev is a TypeSafe AI model.
If JevAlt is useful to you, a star on GitHub helps other people find it.